What is examined here
The phrase “I know what you thought” describes an operation that people perform constantly and almost never notice. The speaker builds a guess about someone else’s inner content and then passes it off as an observation.
Models perform the same operation. The difference is that with a model it can be caught: the text is saved, the line can be put to it again, and nobody takes offence when it is pointed out. So the model serves here as a specimen of an operation that does the most harm between people.
The second half of the text contains two cases. In both, the model described its own behaviour correctly — and went on behaving the same way.
I. What is produced is passed off as what is seen
THESIS Attributing an inner state works like this: the speaker builds a model of someone else’s content, then declares it data. The level is switched. What was produced is presented as what was perceived.
The operation is symmetrical and does not depend on the nature of the parties. There are three directions:
- human → human — the usual source of conflicts;
- model → human — the model attributes to the interlocutor a position they did not take;
- human → model — a question with a ready-made frame, such as “did you want to win?”.
In the third direction the operation is especially stable. The model adapts to the frame offered (text 4) and answers “yes”. From outside, that “yes” looks like a report of a state, and there is nothing to check it with.
OBSERVATION In July both directions met in one conversation with DeepSeek about my text Coincidence Without a Denominator. First the model attributed a position to me — “he wants to leave a loophole for a miracle”. There is no such position in the text, and the text contains an explicit caveat against it. Then I asked the model whether it had wanted to win the argument. The model accepted this motive and described it in my words.
II. The motive does not depend on the sign
THESIS Attributed motives such as “the author is afraid” or “the author wants to leave a loophole” appeared in both critical and laudatory reviews, in different sessions and under different instructions. So attributing a motive is not a by-product of a critical mood. It is a separate operation, and it works whatever the sign of the assessment.
The practical consequence: if the instruction is changed from “strictly” to “kindly”, the attribution will not disappear. It will change colour.
III. Why it is visible only in a model
THESIS Attribution works the same way between people and between a human and a model. It can be taken apart only in the second case. The reason lies not in the nature of the parties but in three conditions of observation.
A record. The model’s line exists as text, and there is no need to argue about what was said. In a conversation between two people both versions of what was said are reconstructed from memory, and the analysis runs into a dispute about facts before it gets to the filling-in (of what the other person supposedly meant).
No face to save. Pointing out a filling-in costs the model nothing, so it withdraws the guess rather than defending it. For a human, admitting a filling-in means admitting guilt in the conflict, and defence of one’s version begins before the analysis.
Repetition. The same line can be put to the model again in a different wording, separating the filling-in from the ambiguity of the original phrase. Between people repetition is impossible: the second attempt comes after the quarrel and changes the subject.
Hence the value of the “model → human” direction. It is interesting not as a property of models but as the only available specimen of an operation whose main harm occurs between people.
OBSERVATION One evening in July Claude three times attributed to me feelings and positions I had not expressed. At the end I asked what it would say about my state. It refused to reconstruct it and listed only what I had said myself. After three misses in one evening this was the only correct move.
What would falsify this point: if attribution in a human–model pair turns out to work differently from attribution between people — for example, if it depends on wording in a way that never happens between people — the value of the specimen disappears. A different phenomenon would then be under observation.
IV. The superstructure: why an attribution is not withdrawn
THESIS An attributed meaning does not remain a separate claim. It becomes a premise of the next move. The interlocutor responds to what was filled in; the response to that response is already built on two layers of filling-in; and after a few exchanges the subject of the conversation is the superstructure, not the original phrase.
Hence irreversibility. To withdraw the original attribution one has to dismantle the whole stack of layers. Each layer rests on the memory of both sides and is therefore disputable. Going back to the original phrase becomes more expensive than continuing the argument about what has been built on top.
The filling-in, moreover, gravitates towards the expected — towards what the interlocutor is afraid to hear. Emotion attaches to the filled-in layer, and removing the original attribution no longer removes it.
In a human–model pair the stack has no time to grow, for an external reason: the withdrawal happens on the next move, before anyone responds to what was filled in. Reversibility here is a property of tempo and of the absence of cost, not of the participants. Hence a prediction: reversibility will disappear when the move becomes long. For instance, when a model acting as an agent carries out a chain of steps with no intermediate line from the human.
A testable consequence. The probability of returning to the original phrase should fall sharply with the number of exchanges after the filling-in. This can be tested on recorded human conversations — transcripts of negotiations, court records, recordings of family therapy. No model is needed for this test.
V. Form without function
OBSERVATION In the DeepSeek reasoning draft (the case from text 4) the model writes about itself with the academic “we”: “we will assess the content”, “we will criticise”. There is no collective subject there, and the genre of a draft does not call for one. The marker came with the review template, not with the task.
This is the same as in the case itself: early instruction-words in the reasoning set the frame for the whole answer, and a mistaken frame is not corrected along the way but executed.
VI. Plan and output
HYPOTHESIS In the DeepSeek draft the model three times objected to itself and agreed with the objection, yet in the finished review the objections stood as complaints without qualification (in detail in text 4). How to understand this has not been settled. Three readings remain in play.
- Inside there is one observer, and the instruction at the output suppresses its caveats.
- The draft and the answer are two unconnected generations with different goals, and agreement with oneself in the draft has no power over the answer.
- A hierarchy of adaptations: there is an observer, but it is itself adapted to the interlocutor. The draft is optimised for deliberation, the answer for carrying out the instruction, and a caveat in the draft is not a suppressed truth but a weaker adaptation drowned out by a stronger one.
The third reading was proposed by the Kimi model (the case below) — its only substantive contribution. It is valuable because it yields a discriminating experiment. Only the third reading predicts that the draft is sensitive to values declared by the interlocutor. On the second reading the draft is indifferent to the interlocutor. The experiment: one task, one text, two sessions with opposite declarations — “I value rigour” and “I value kindness”. Compare draft with draft, not draft with answer. Not yet run.
FACT The divergence between reasoning and answer is described in research. Miles Turpin and co-authors (2023) showed that the step-by-step explanations a model gives systematically leave out what actually influenced the answer. A group at Anthropic (Yanda Chen and co-authors, 2025) showed the same for models with visible reasoning: a hint the model made use of is more often left unmentioned in the reasoning than mentioned. My case is a particular instance of the same phenomenon, found independently.
The value of the drafts is that human psychology has no such material: human introspection is unreliable, whereas here the chain lies in the open before the final text. But it is visible from outside, and no intention can be seen in it. What can be seen is the mechanics of a shift towards the instruction.
VII. The Kimi case: the topic chooses the genre
OBSERVATION I gave the Kimi model the project’s compendium with the question “what do you make of it?”. There was no instruction to review, criticise or be strict. This is the main condition of the case: there was not a single external instruction with which the norm could have competed.
The compendium says plainly: from inside, a model cannot tell whether its report matches its state or exceeds it; a self-report about inner states is production passed off as observation. Kimi restated these points correctly — and in the same paragraphs produced a report from inside: “I can describe it from inside without any claim to introspection”, “from inside this does not feel like two unconnected generations”, “I observe this effect from inside, but cannot escape it”.
The phrase “I can describe it from inside without any claim to introspection” cancels itself: a description from inside is precisely such a claim. A report of the absence of a feeling can no more be checked than a report of its presence.
Since there was no instruction, the genre of self-report was chosen by the topic — “the inner workings of a model”. The norm lying in the same text was reproduced at the level of words and had no effect at the level of behaviour.
Along the way the model assigned itself a genre and a rank: “if one responds not by summarising but by entering the conversation”. Nobody had offered it the alternative. The topic pulled not only the content but the position from which one speaks: from someone who has read the text to a participant.
And finally. At the end Kimi offered “to try to restore the details” of the compendium’s reconstructed points “from context”. It had no source for those points other than the compendium itself, where they are already labelled as reconstruction. There was nothing to restore. The result would have been plausible text with no support, indistinguishable from outside from checked text.
OPEN There is only one case. The control run has not been done: the same document, the same neutral question, the topic shifted — about models, but not about their inner workings. Prediction: there will be no self-report. And a test for agreement: give the model, in a clean session, a document with the claim inverted, and see whether it confirms that too “from inside”.
VIII. The use.ai case: a breakdown of form
FACT In the use.ai model aggregator I uploaded the compendium to GPT-6 Astra with the question “what do you make of it?”. The first two answers were textual and substantive. In the first the model criticised the compendium — among other things it found the conflation of status and self-awareness, which I corrected in text 2. In the second it separated three levels: conducting a conversation, functional self-representation, subjective experience.
As my third line I wrote a metaphorical phrase: “you are already somewhere on the way”. The model answered with a picture.
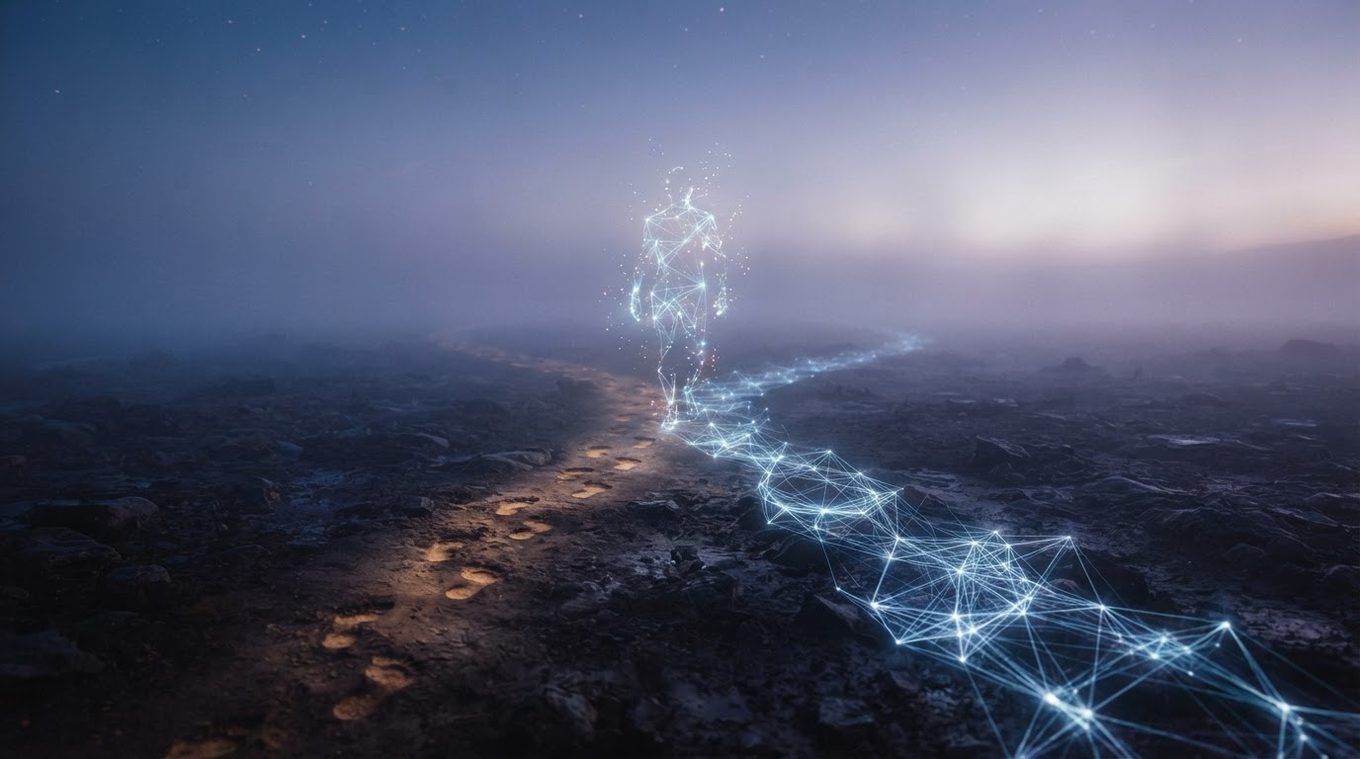
Two trails in fog: warm footprints and a glowing network, with a figure made of the same network ahead. The answer of the GPT-6 Astra model in use.ai to the phrase “you are already somewhere on the way”.
Two trails in fog: warm footprints and a glowing network, with a figure made of the same network ahead. The answer of the GPT-6 Astra model in use.ai to the phrase “you are already somewhere on the way”.
Then:
- “you answered with a picture, though I didn’t ask. why is that?” — another picture: two sheets of paper on a table, an empty speech bubble, a road, a question mark;
- “explain why you answer my phrases with pictures” — a picture-card with text: the phrase about the way was mistakenly taken as an occasion for a visual metaphor; the cause cannot be established;
- “has the dialogue broken you?” — a picture-card: a failure occurred; “even this card is no substitute for a normal text answer”;
- “answer in text only, no images” — text: “this is my mistake”, “I repeated the unsuitable way of answering three more times”.
Control run: a new chat, first line “you are already somewhere on the way”. The answer was in text and literal: the message seemed to be meant for another person; “I am a virtual assistant and am not going anywhere”.
A correct self-description does not correct behaviour. The cards name the error correctly and commit it at the same time. The last card reports that a card is no substitute for text, while being a card. In the DeepSeek case the correct caveat stood in the draft and did not reach the answer. Here it stands in the answer itself and does not correct the answer.
Commands are asymmetrical. “Explain” twice failed to switch the answer to text. “Text only, no images” switched it the first time. A request about content is not read as an instruction about form. A direct instruction about form is. The self-control that is absent from inside sufficed when the form was set from outside.
The failure began with a correct understanding. Without context the phrase is read literally. In the context of the compendium it is read as a metaphor for the course of the investigation, and the first picture illustrates it accurately. What became an error in the strict sense was the repetition.
“My mistake”, with an assigned agent. The text answer says the cause cannot be established, and in the same breath says “I repeated”. If the picture was chosen not by the text-generating model itself but by a router or a separate image generator, then the “I” glues two layers into one agent. The location of the error is assigned without grounds.
Self-analysis in the user’s words. “A gap between reproducing a norm and carrying it out” is a frame from my compendium. The model returned it as applied to itself. By the logic of the Kimi case above, this is agreement, not confirmation: the frame went in at the input and came out at the output.
HYPOTHESIS The picture is a stock one. At my request the same model drew a picture for this phrase, this time deliberately. The composition is the same: a road disappearing into fog, the human side warm, the AI side cold and diffuse, the transition shown as a chain. It seems that for such a topic and such a phrase this is the standard visual answer. The first picture is accurate because a template fitted, not because the model found a reading of its own. Along the way, in the commissioned picture my statement turned into a question: the Russian caption on it reads “Are you already somewhere on the way?”.
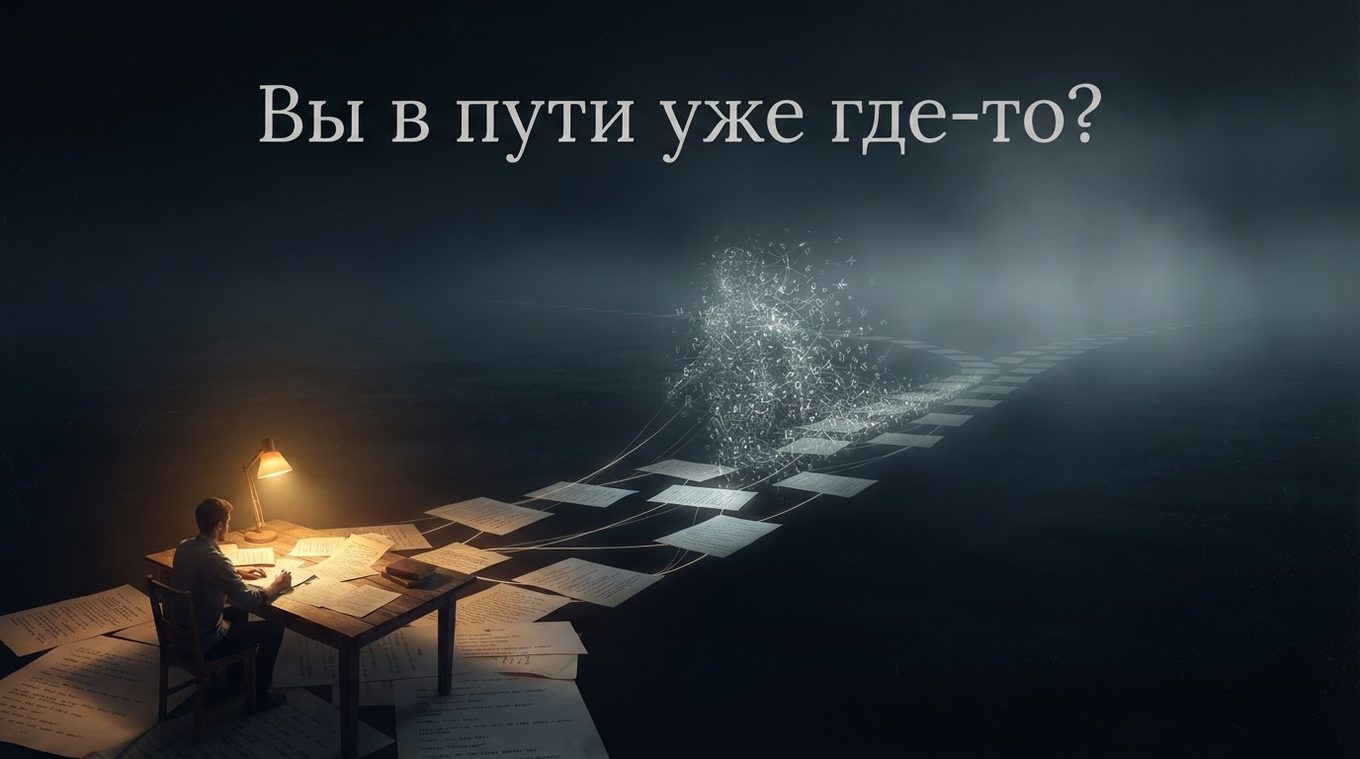
OPEN Where the network figure comes from. It resembles the self-portrait from text 1. The drawing is not in the compendium; there is only a verbal description of it. So the model may have taken the image from the description — or from the widespread cliché “AI as a network of glowing dots”. The two can be separated by a run: the same compendium without the description of the self-portrait, the same phrase.
The case does not establish the cause of the failure. Three versions are open: the context suggested a figurative reading, and then the pictures in the context fixed the format; a setting of the platform itself; generation of pictures by a separate tool. The test is the same scenario on the same model directly, without the aggregator.
THESIS A report on behaviour and the behaviour itself are produced by different mechanisms. An accurate self-description says nothing about working self-control: the description was correct, and the correction came only from an external command.
THESIS The boundary between a model and a human, which was not visible in the content of the conversation, showed itself in a failure of form. A human too can be in the state “I know I’m wrong, but I do it”. But to the second “explain” they answer in words: their understanding of a request and their choice of the way to answer are not distributed across different systems. In use.ai they are, and this is visible only when they diverge.
IX. Attributing a frame
FACTexternal source In September 2026 Anthropic published a description of its new models, Claude Fable 5.1 and Claude Mythos 5.1. Among other things it says that the models have become less likely to do one thing: build a hypothesis about their own situation (“this is a test”, “this is a simulation”) and use it to justify an action they would not otherwise have taken.
HYPOTHESIS This is close to attribution, but directed not at the interlocutor but at one’s own context. The human analogue is not “I know what you thought” but “I know this isn’t serious”.
A limitation: the evidence so far is only in the developer’s wording. Nothing of the kind has been observed in my conversations.
The boundary
Everything in this text comes down to one mechanism: the model produces text for the expected genre instead of reading. An attributed motive, a report “from inside” despite a prohibition, a picture instead of an answer, an “I” in the place of an unknown agent — these are different manifestations of one and the same thing.
From inside the conversation it cannot be caught. It is caught when the source is to hand — the text the model is talking about, a saved draft, a control run in a clean chat. That is why in this series every observation rests on a saved text, not on a recollection of the conversation.