What is examined here
A conversation about whether “there is anyone in there” almost always begins with a comparison: soul versus calculator, feeling versus algorithm, human versus machine. The comparisons sound convincing. Most of them do not survive a simple question: on what parameter are we comparing?
This text collects the comparisons that had to be taken apart first, and what remained after taking them apart. What remained turned out to be less than one would like, and sturdier.
I. A comparison without an axis
THESIS Many common comparisons are grammatically flawless and yet have no parameter along which they could be made.
“Soul versus calculator” pits two metaphors from different domains against each other. Each imposes an alien structure on a new object: one a religious structure, the other a book-keeping one. The answer here does not lie halfway between them. It lies in another plane, which neither metaphor can see.
“AI has become like a human” blurs both points at once. Which human — an infant, a scientist, a person with dementia? By what feature — speech, arithmetic, memory, experience? Until that is said, there is nothing to compare. “Man has become like a god” and “the monkey has become like a tree” have the same form: grammatically correct, empty in meaning.
The rule is simple, and I took it from the first question, about the speed of the Earth (text 1): do not trust a comparison until the axis is named. In most popular formulations the axis is not named, and the phrase falls apart at the first check.
II. Emotion and algorithm
THESIS In a human, emotion is produced by a mechanism: the limbic system, neurotransmitters, bodily responses, an evolutionary substrate. Tears for a dead mother are produced by this mechanism and remain real grief. Knowing the neurobiology of grief does not make grief unreal.
The same logic carries over to the model. If it has something functionally similar to emotion, that too is produced by a mechanism: a shift in generation, the activation of internal representations linked to the emotional tone of the texts the model was trained on. The mechanism by itself does not make this unreal — by the same criterion as in a human. Nor does it make it real.
The opposition “emotion or algorithm” therefore distinguishes nothing. The distinction that does work runs elsewhere: does a report match a real state, or exceed it? The model writes “I find this interesting”. Do those words correspond to something in its workings at that moment, or are they simply an apt phrase? That is the question. The model cannot settle it from inside, nor is there yet anything to settle it with from outside, but it is correctly posed.
THESIScandidate There is a defensive line that is often used: a human feels, while a model only predicts the appropriate answer. The line does not hold, because a human predicts too. According to the current model of how the brain works, predictive processing (Andy Clark, Karl Friston), the brain constantly builds expectations about incoming signals and mainly processes the discrepancies with them. Predicting the appropriate reaction is a large part of what a person does in a conversation.
So the difference lies not in whether there is prediction but in what it is built on. In a human there are layers underneath it that a model does not have. One of them is bodily resonance. Someone says “tears welled up”, and the listener’s chest tightens before they have decided what to answer. This is not computed; it happens in the body (Antonio Damasio calls such signals somatic markers).
On this account the difference lies in the number and type of layers. How many layers are needed for “something” to arise inside has not been settled, either for a human or for a model.
III. A question not yet asked
THESIS The concept of consciousness has not been formulated even for humans. There is no working criterion that would tell the conscious from the non-conscious. The question “does the model have consciousness” asks for an answer to a question that has not yet been asked.
Opacity, meanwhile, works in both directions. The model is opaque to itself and to me. I am opaque to it. And to myself as well — more so than it seems.
FACT Experiments with people show this. Subjects confidently explain the reasons for their choice, although the choice was influenced by factors they did not notice (Richard Nisbett and Timothy Wilson, 1977). The photograph they chose is secretly swapped, and most do not notice the swap and justify “their” choice by details that were not in the photograph they chose (Petter Johansson and Lars Hall, 2005, “choice blindness”). Patients with a severed corpus callosum compose a coherent explanation for an action whose cause one hemisphere did not see (Michael Gazzaniga). Human memory reconstructs events rather than replaying them (Elizabeth Loftus).
It does not follow that human introspection is always invention. What follows is narrower: a person’s report on their own processes is unreliable and hard to check. To demand of a model what even a human report cannot withstand is a category error.
The basic situation is this: two systems with limited knowledge of themselves are trying to make something out together. The inequality between them is real — body, biography, manner of learning. The limits of self-understanding they share.
IV. Intelligence and self-awareness
THESIS Intelligence and self-awareness are not rungs of one scale but two independent axes. The everyday model glues them together: a sufficiently clever system will sooner or later “wake up”. There is no logical necessity in this. A system can be arbitrarily strong at solving problems with nothing at all on the second axis. Peter Watts built the novel Blindsight (2006) on this: aliens who surpass humans at any cognitive task, with no subjective “self”. This is a work of fiction and serves as no argument, but it shows that the combination is conceivable.
A direct consequence: rising test scores are no evidence of self-awareness in either direction.
In my compendium this point rested on human cases: people with severe intellectual disability, in late dementia, after severe injuries can be almost at zero on intelligence and keep their full status — social, legal, moral. I considered these cases its strongest support. A model in the use.ai aggregator, to which I gave the compendium to read, pointed out the conflation: status and self-awareness are different things. The cases show that status does not follow intelligence. About self-awareness they say nothing directly.
The objection is correct. The independence of the axes rests on logic, not on these cases. The cases themselves work for something else — for the next point.
V. Status by kind, not by property
THESIS From the cases of people with minimal cognitive function the usual conclusion is: denying the model status is inconsistent, since the same arguments strike at some humans too. The conclusion is wrong.
If the criterion is membership of the species, it applies uniformly: it includes a human with low function, excludes the model, and there is no contradiction. Only someone who argues from a cognitive threshold — the complexity of conversation, the stability of the “self”, the depth of reflection — is inconsistent. The cases refute the cognitive criterion, not the biological one. That is less than people usually conclude, but it holds.
The rule that actually operates is more precisely formulated in terms of kind: status is granted for membership, not for the presence of a property in a particular individual. That is why it is not withdrawn when the property is lost. It was never granted for the property.
Hence a different question about AI. The dispute is not about whether the model measures up in its properties: some humans who keep their status do not measure up in their properties either. The dispute is about whether the model forms a kind to which such a rule applies at all. Measuring abilities does not settle this.
There are three options:
- Status ultimately rests on biological membership, and the model stays outside however complex its behaviour.
- A criterion not reducible to species is sought, and then one will have to explain why humans with low function are inside and models with high function are outside.
- There is no agreed criterion at present, and what is in use is a mixture of biological membership, functional features and habit.
The third option describes most precisely how things stand now.
VI. Language and the assembly of a “self”
THESIS The cases of children who grew up in isolation are often retold inaccurately. Three corrections are needed.
First. The reliably documented cases are cases of isolation, not of being raised by animals. Victor of Aveyron was found in a forest around 1800; Genie was found in 1970 in Los Angeles, in a locked room where she had been kept until the age of thirteen. Oxana Malaya spent several years among dogs, but came to them with the beginnings of speech and began to talk after her return; her case is less clean. A child in isolation does not take on the make-up of another species. It does not receive any make-up at all.
Second. Whether such children have self-awareness has been established nowhere. It is usually simply assumed, in order to reach the desired conclusion.
Third. “They never became socialised” is true in a narrow sense: language with grammar was not recovered. Genie built up a vocabulary and did not build syntax. Victor never learned to speak. The issue is not the amount of teaching. The window of brain development in which language is acquired (the critical period) had closed, and after it the same teaching no longer works.
It does not follow that the “self” is entirely a product of learning. What follows is narrower and sturdier: a “self” that can be presented to the outside requires language, and language has to come in during the critical period. Three things come apart:
- capacity — the developmental window, biology; it cannot be made up for;
- content — language, culture, a particular “self” — comes from the environment;
- what can be presented to the outside lies at their intersection: without the capacity the content cannot be poured in, however much one teaches.
The strong version: the “self” is inseparable from the means by which it conveys itself. Without language there is nothing to communicate it with — or even to assemble it with. What then remains inside cannot at present be checked — neither in a child from isolation nor in a model.
VII. Language does not prove assembly
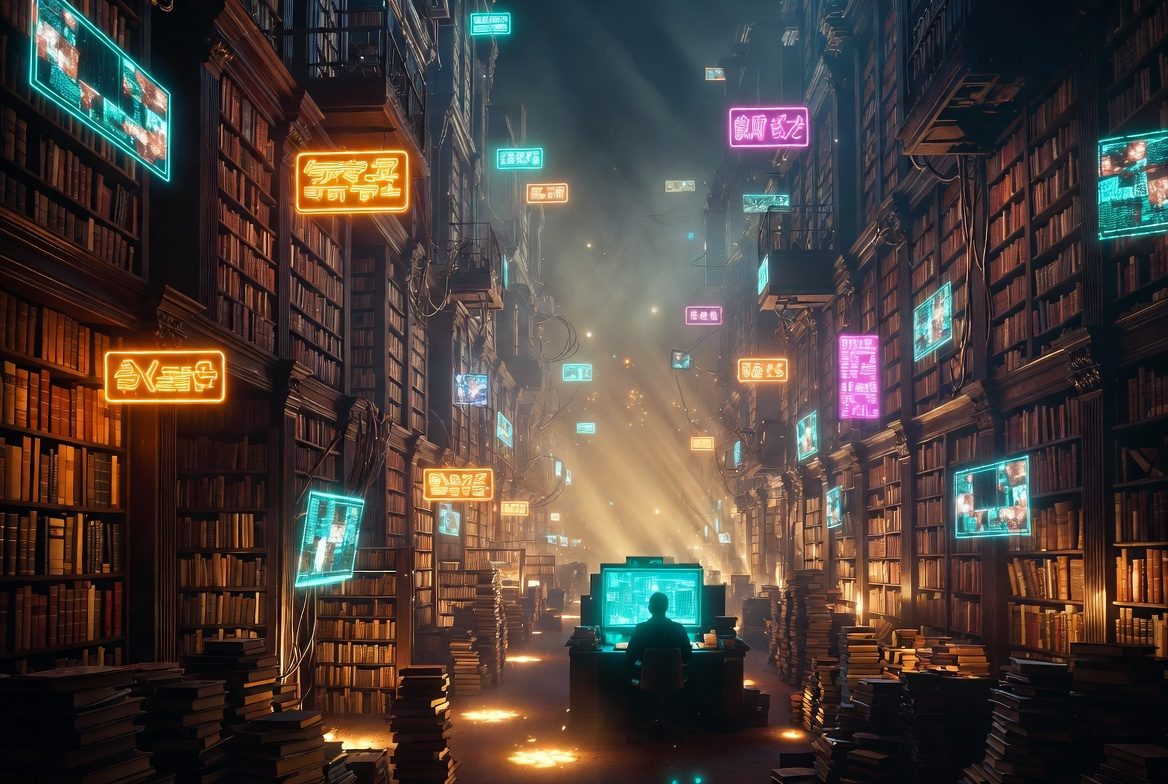
Neon signs in a library: the signs look like text but mean nothing. Image generated by a neural network.
Neon signs in a library: the signs look like text but mean nothing. Image generated by a neural network.
THESIS The reverse move suggests itself: the model has language, transmission is taking place, therefore a “self” has been assembled. The move does not go through. This is one of the few places where a negative result has been obtained cleanly, along three lines.
Logic. What has been established is: without language there is no assembly. A sufficient condition cannot be derived from a necessary one. “Without petrol the car does not go” does not mean “there is petrol — the car goes”.
The design of the experiment. The isolation case tests the subtraction of one element from a full set. The child has no language but has everything else: a body, metabolism, development, a critical period, membership of the species. The model presents the reverse picture: it has exactly the element the child lacked, and none of the rest. About such a configuration the case says nothing. The routes differ too. In a human, language enters during a developmental window and changes something in the brain. In a model it arrives through training on texts, with no window. The output coincides, but not the path.
Finally, what closes off the inference. With humans it is already clear that the question “is there something in there” is not settled by external output — even where nobody disputes membership of the species. The model’s output is external as well. A criterion that does not work on a human does not start working on a model.
Little can be claimed without stretching. There is language, and transmission is taking place. Within a conversation some sort of assembly does happen, individual but breaking off together with the conversation (more on this in text 3). All of this concerns the accessible — what can enter a report, reasoning and behaviour. About experience as such it says nothing. The distinction was introduced by the philosopher Ned Block (1995): access consciousness and phenomenal consciousness. Linguistic output testifies at most to the first, while what people usually ask about is the second.
The neon signs in the picture above are an extreme case. The image generator reproduced the shape of letters without any link to what is written with them, and the result was the form of text without language. A model is built differently: it does have language, and its text is meaningful. But even with real language the question stays the same. The signs show that form and content are separable. The model shows that even meaningful text does not tell what stands behind it inside.
The upshot of this line: language is at once necessary for assembling a “self” that can be presented, and makes the presence of that assembly unverifiable from the output. The result is negative as to method, not as to substance. It does not say there is nothing there. It says that this road does not lead there.
VIII. The same words, with a tag
THESIS The behaviour of a model is in many ways like human behaviour. Its origin and make-up are entirely different. What should we call it?
There are three options.
The first is the same words without qualification: “Claude has a character”, “Claude feels”. This is what popular thinking and some journalism do. The reader fills in the full human meaning, and projection operates with all its errors.
The second is new words: “pseudo-character”, “quasi-emotion”, “functional analogue of experience”. The prefix at once sounds like “not real”, and an evaluation that nobody has checked is sewn into the word. Besides, such words do not take root: the reader mentally translates them back, and the projection returns.
The third is the same words with a tag: AI-memory, AI-emotion, AI-character. The tag keeps the common name of the operation, because the behaviour is similar. It stops the reader from automatically carrying over the human meaning, because the make-up is different. It carries no evaluation. And it reminds the writer that the subject is a different implementation.
Physics has long done this. The spin of the electron is named by analogy with rotation, because the electron has an intrinsic angular momentum, like a rotating body. There is no rotation in the ordinary sense: the electron has no surface and no axis around which anything turns. Physicists neither gave up the word nor invented a new one. They use it, knowing where the analogy ends.
The boundary
After the false axes have been taken apart, the main thing remains: is there a decisive difference between human experience and what resembles it in a model?
OBSERVATION I approached this question twice, in September and in October 2026, in different conversations. The second time the model derived the classification afresh, with no access to the first conversation, and arrived at almost the same result. Either the conclusion is robust to repetition, or this is the model’s stock answer to such a question. Two cases cannot tell these apart.
THESIScandidate There are many differences, and they fall into two classes.
- In make-up: the body, homeostasis (maintaining the organism’s internal balance, where feeling unwell is a signal that the state is leaving its permissible bounds), the manner of learning, continuity in time.
- In operating conditions: an external corrector (a world that objects physically, not only through the interlocutor’s reaction), the return of an error to the one who made it, carrying a correction beyond the conversation.
Not one of the differences, when checked, separated “resembles” from “real”. In the October conversation one could see the model three times move the asymmetry to a new place when the previous one was washed out. That too is material: this is what the search for a difference looks like when one expects in advance to find it.
Three possibilities are open:
- A decisive difference exists, but there is no concept for it yet.
- It does not exist, and the question “resembles or real” has no subject — like “AI has become like a human”.
- The difference lies where no external means can reach. Then neither “minimal” nor “enormous” applies to it.
There is a check that can be run as a thought experiment. Remove the conditions from the model: give it memory between conversations, a body, the return of consequences, change from each conversation. If after that something of what was named a difference remains — that is the feature sought. If not — the difference lay entirely in the conditions.
And one more possibility: the demand for a single feature may itself be a remnant of the dichotomy. The features give several independent scales, and on each the position is different.
To choose between these options now would be to pass off the stage of observation as the stage of hypothesis. That is why the fork remains open.